Stood up the LLM inference and RAG infrastructure for a growth-stage product — multi-provider routing, streaming responses, semantic caching, and an evaluation harness that took "ship a prompt change" from a release to a ~5-minute task. Inference cost down ~40% against their v1 build.
Available for new engagements —
next quarter
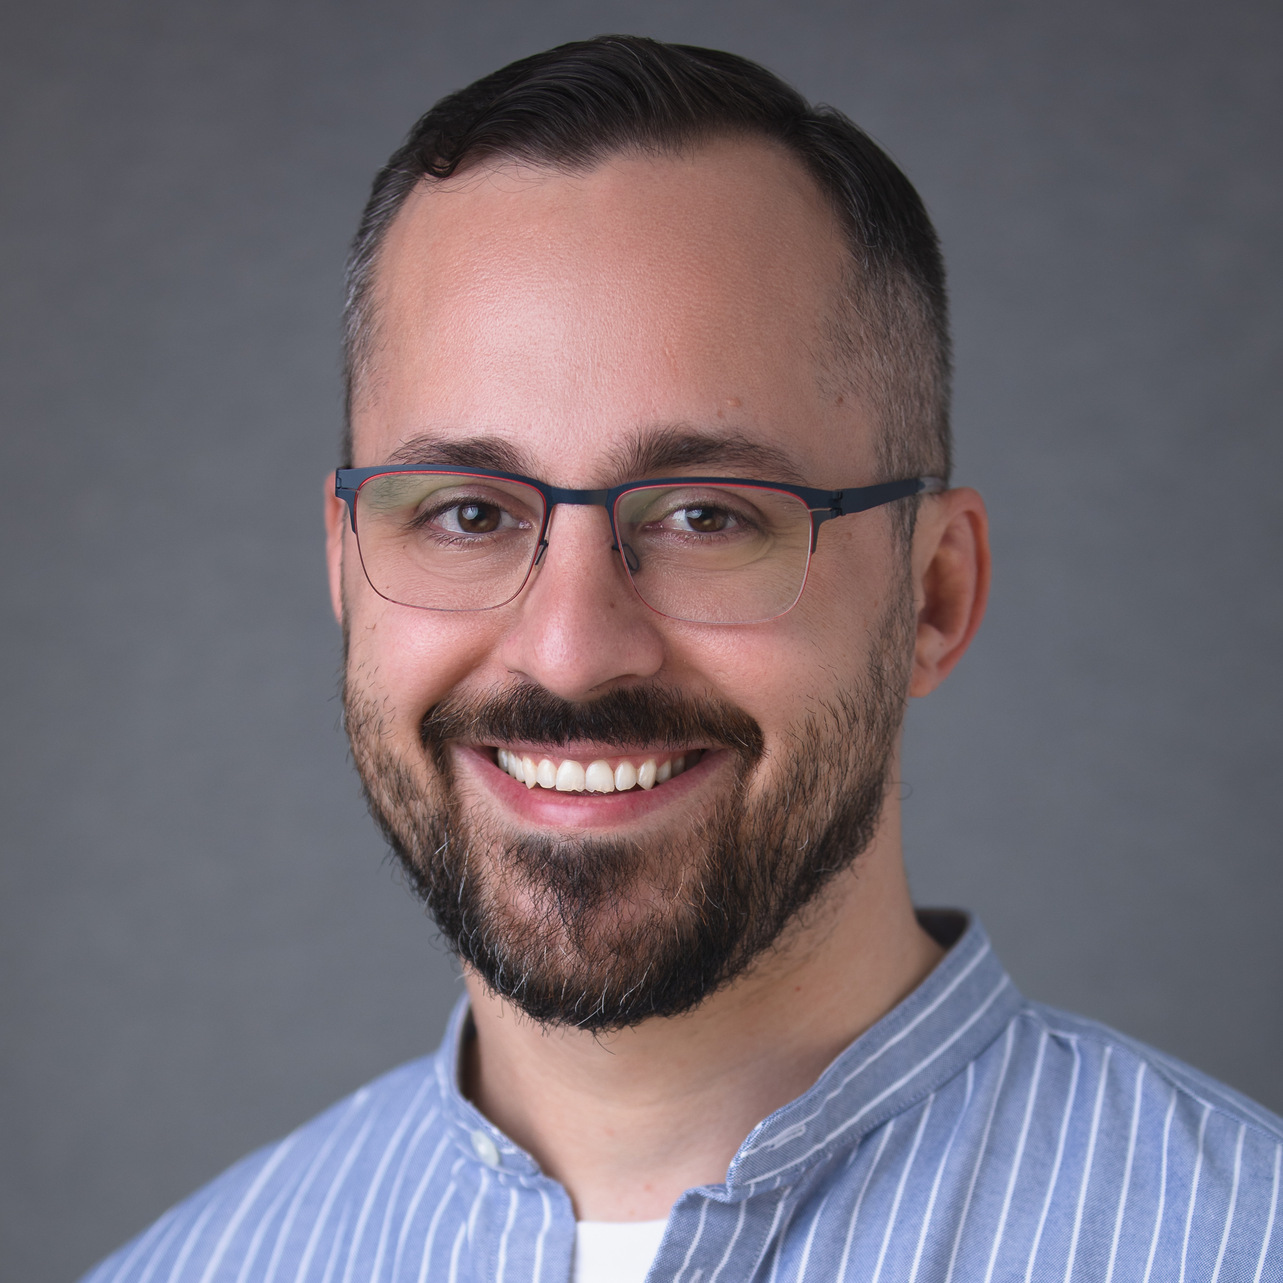
Denys Malykhin
Principal engineer for venture-backed teams. Production backends, AI agents and LLM systems, cloud infrastructure, and the systems work that keeps a growth-stage product upright. Based in Vancouver, working remotely with teams across the US, Israel, and Europe.
What I do
Backend & distributed systems
Production services, APIs, and async workflows, with the observability to see what they're doing. Built to hold up under load and to be understood by the team that inherits them.
AI agents & LLM systems
LLM features and agents that hold up in production: RAG, tool-using agents, MCP integrations, multi-provider routing, and the evals and cost controls that keep them honest.
Cloud infrastructure & cost
Architecture across compute, data, and the cloud bill that comes with it. Right-sized environments, not over-engineered ones.
System architecture
Designs aimed at the next 18 months of product, not a whitepaper for year five. Pragmatic boundaries, clear failure modes, room to move.
Codebase & team audits
An honest read on what's working and what's quietly costing you. Findings written for engineering leadership, with priorities you can act on.
TypeScript · Node.js · Java · Python · AWS · Kubernetes · Terraform · OpenTelemetry · LLM APIs · MCP
Selected work
Rolled out OpenTelemetry across the platform and replaced a tangle of ad-hoc dashboards with traces engineers could actually read. MTTR on production incidents dropped from ~2 hours to under 20 minutes; on-call escalations roughly halved over the next quarter.
Re-architected the event pipeline off a misused streaming stack and brought the cloud bill down 78% — from roughly $340K to $75K annual run rate, with no loss of throughput.
Stabilized a checkout service mid-incident. Eliminated ~90% of timeout errors and rebuilt the connection-pool and retry layer the team had been working around for a year.
Designed and shipped the multi-tenant backbone that carried them from 12 to 400+ paying customers without a re-platform. Still in production three years later.
Things I've built
A self-hosted AI agent on your own machine that you use from your phone over peer-to-peer WebRTC. Local LLMs, RAG over your documents, scheduled skills. No cloud, and your data stays on your hardware.
An AI agent for a headless Raspberry Pi, run from your phone over BLE. Describe a goal in plain English and it plans and runs the shell commands while you watch. The Pi never needs a network.
Plug in a Pico W or ESP32 and Claude Code, or any MCP client, can program and drive it from a chat. Per-device mTLS on AWS IoT Core, provisioned from the browser.
Contact
For new engagements, audits, or a second opinion on an architecture call — email or grab a 30 minutes on the calendar directly. Replies within one business day.
denys@malykhin.dev